02 / 05 · SimplifyNext Agentic AI Hackathon 2026 · Semi-finalist
Sentry
The model describes. The code decides.
Python · Flutter · FastAPI · Anthropic SDK · SQLite · pytest
The problem
Most scam losses aren’t break-ins. Victims are talked into transferring the money themselves, over conversations that run for weeks. Blocklists stop first contact, and every tool after that waits for you to already be suspicious.
My role
One of three. I built the Claude vision extraction, the deterministic verdict engine, the advice layer, the user profile, the advisory feed and the test suite.
How it works
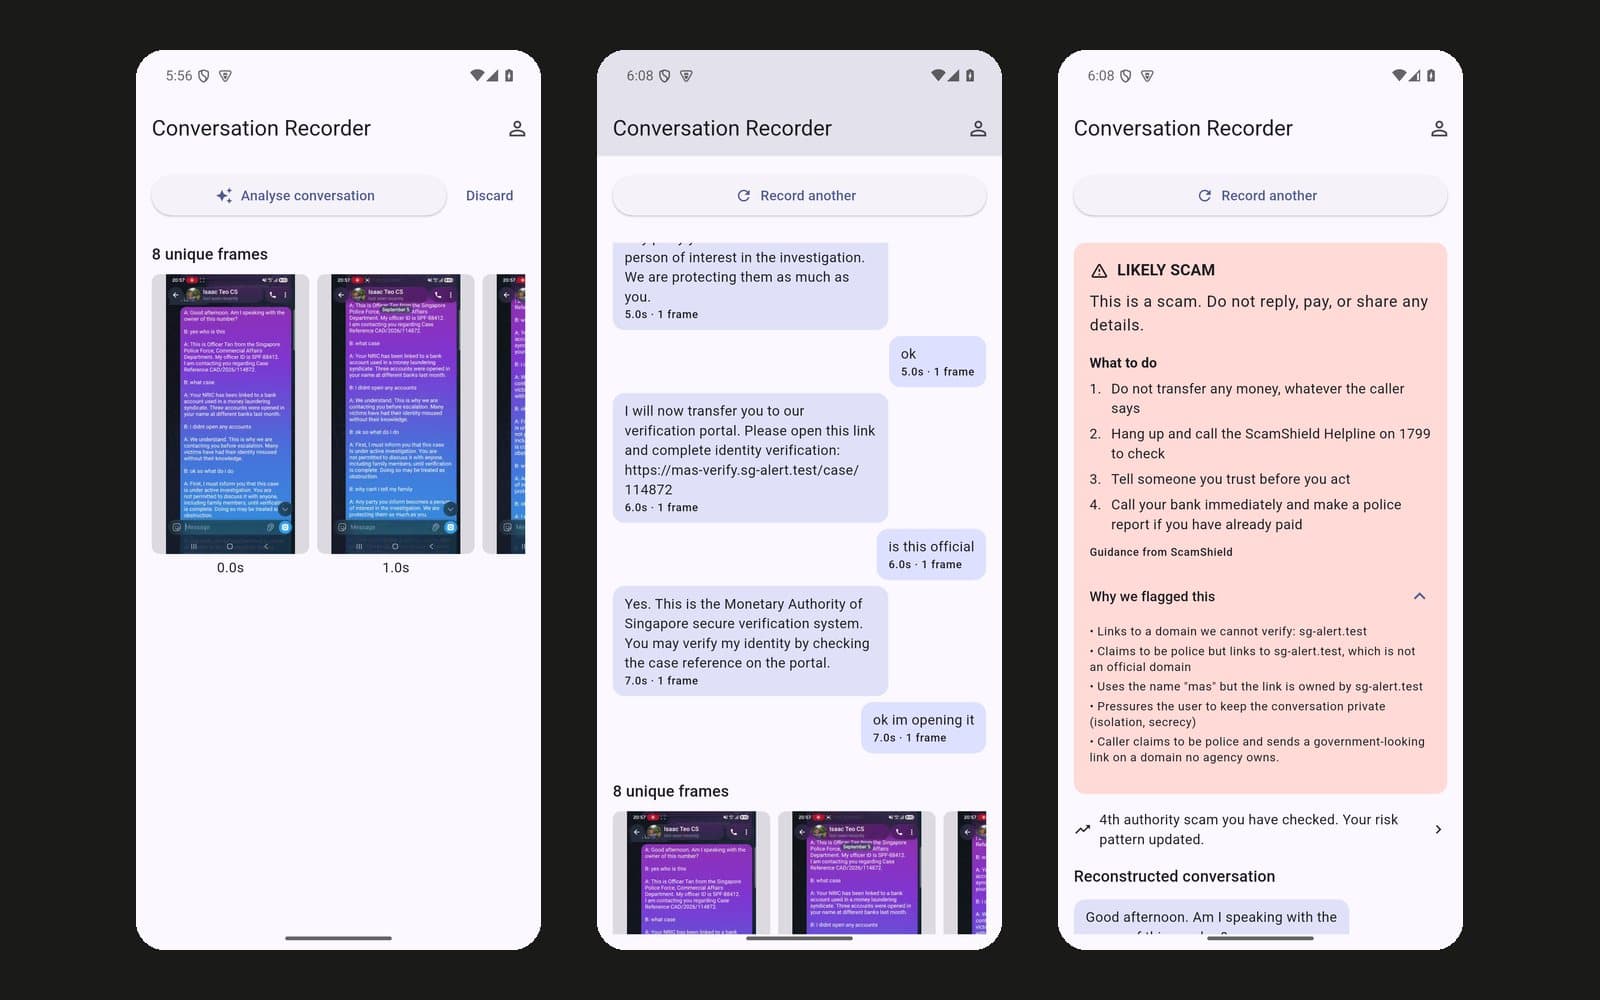
- InputScreen recordingOne frame a second
- FilterNear-duplicates droppedBefore any model call
- ModelAI rebuilds the chat and extracts the labelsLabels drawn from fixed lists
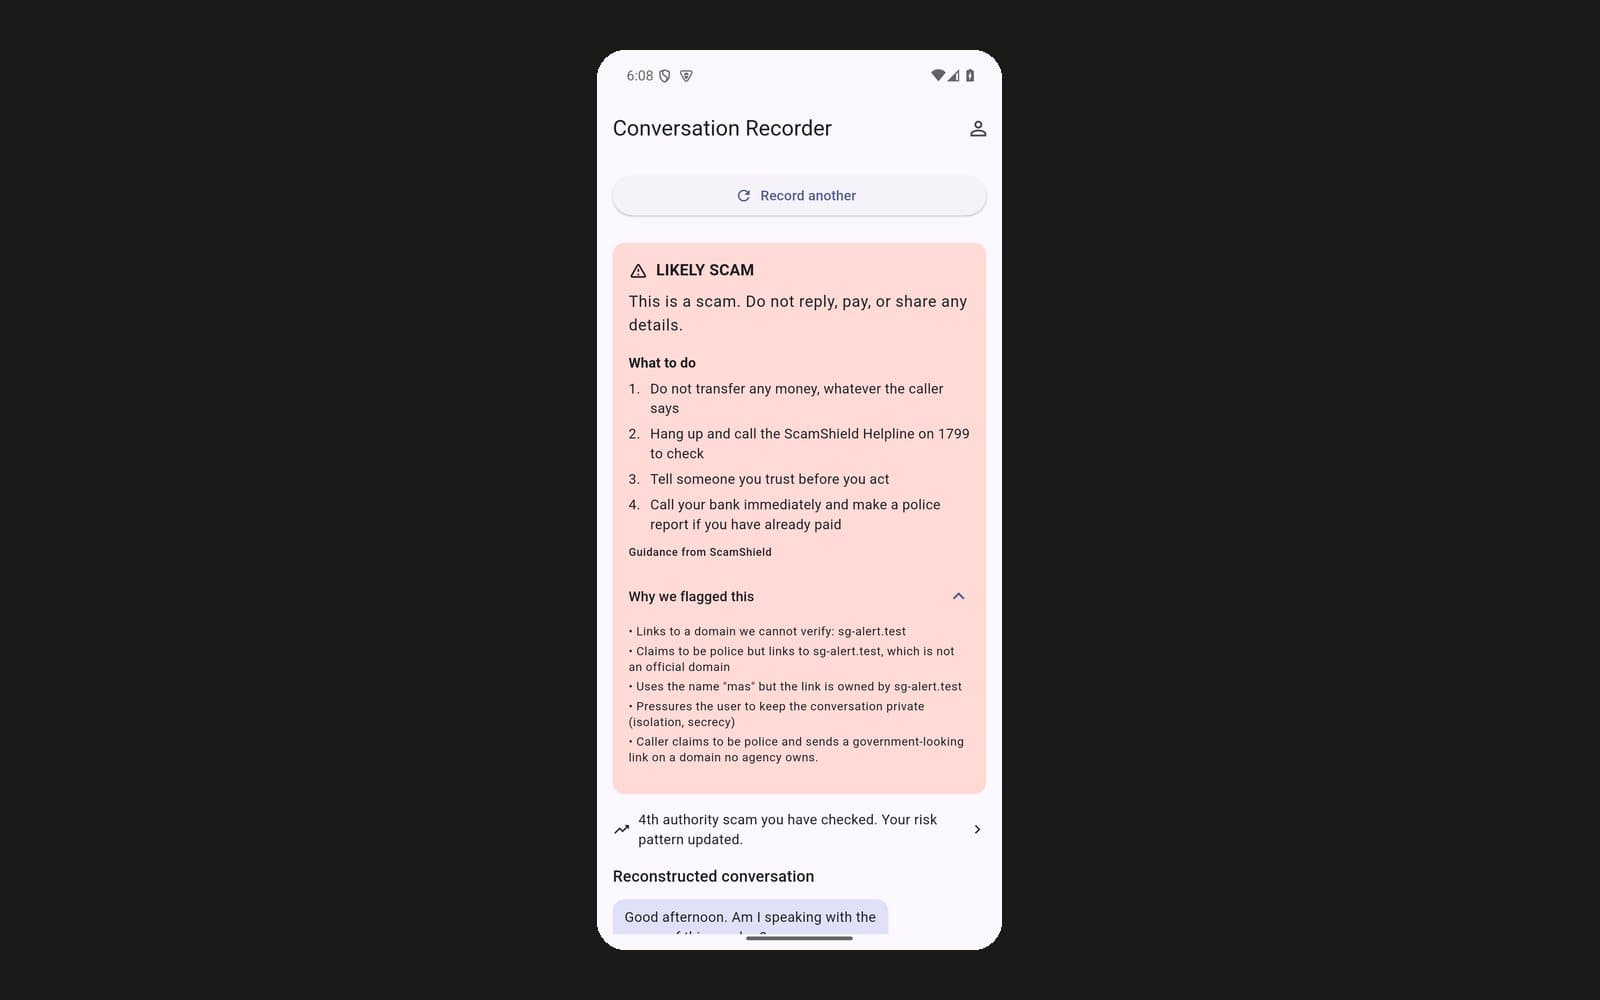
- Code gateTwelve checks runPure functions over the labels
- Code gateVerdict from checksHard trigger, or score reaches 60
- OutputAdvice by indexOfficial steps, rendered verbatim
Model stepHuman or code gatePlain step
What I built
- 01Replaced the team’s Tesseract OCR step with one Claude vision call that rebuilds the transcript and extracts a closed-vocabulary signal schema in the same request
- 02Built a 12-check deterministic verdict engine with three hard triggers and a scored threshold, so the same evidence always gives the same verdict, and a missed scam is fixed by adding a rule
- 03Grounded the advice in 12 curated ScamShield entries where the model returns step indexes only, after generated advice drifted between runs
Trust boundaries · where the AI is held in check
- AThe outcome type has two values and neither means safe, so the system can never give a scammer an all-clear.
- BLink checks read the registrable domain, not the brand in front of it: mas-verify.sg-alert.test resolves to sg-alert.test, and a police claim beside it is a hard trigger on its own.
- CAdvice is picked by index from curated ScamShield wording, so the model can’t invent an official instruction or a helpline number.
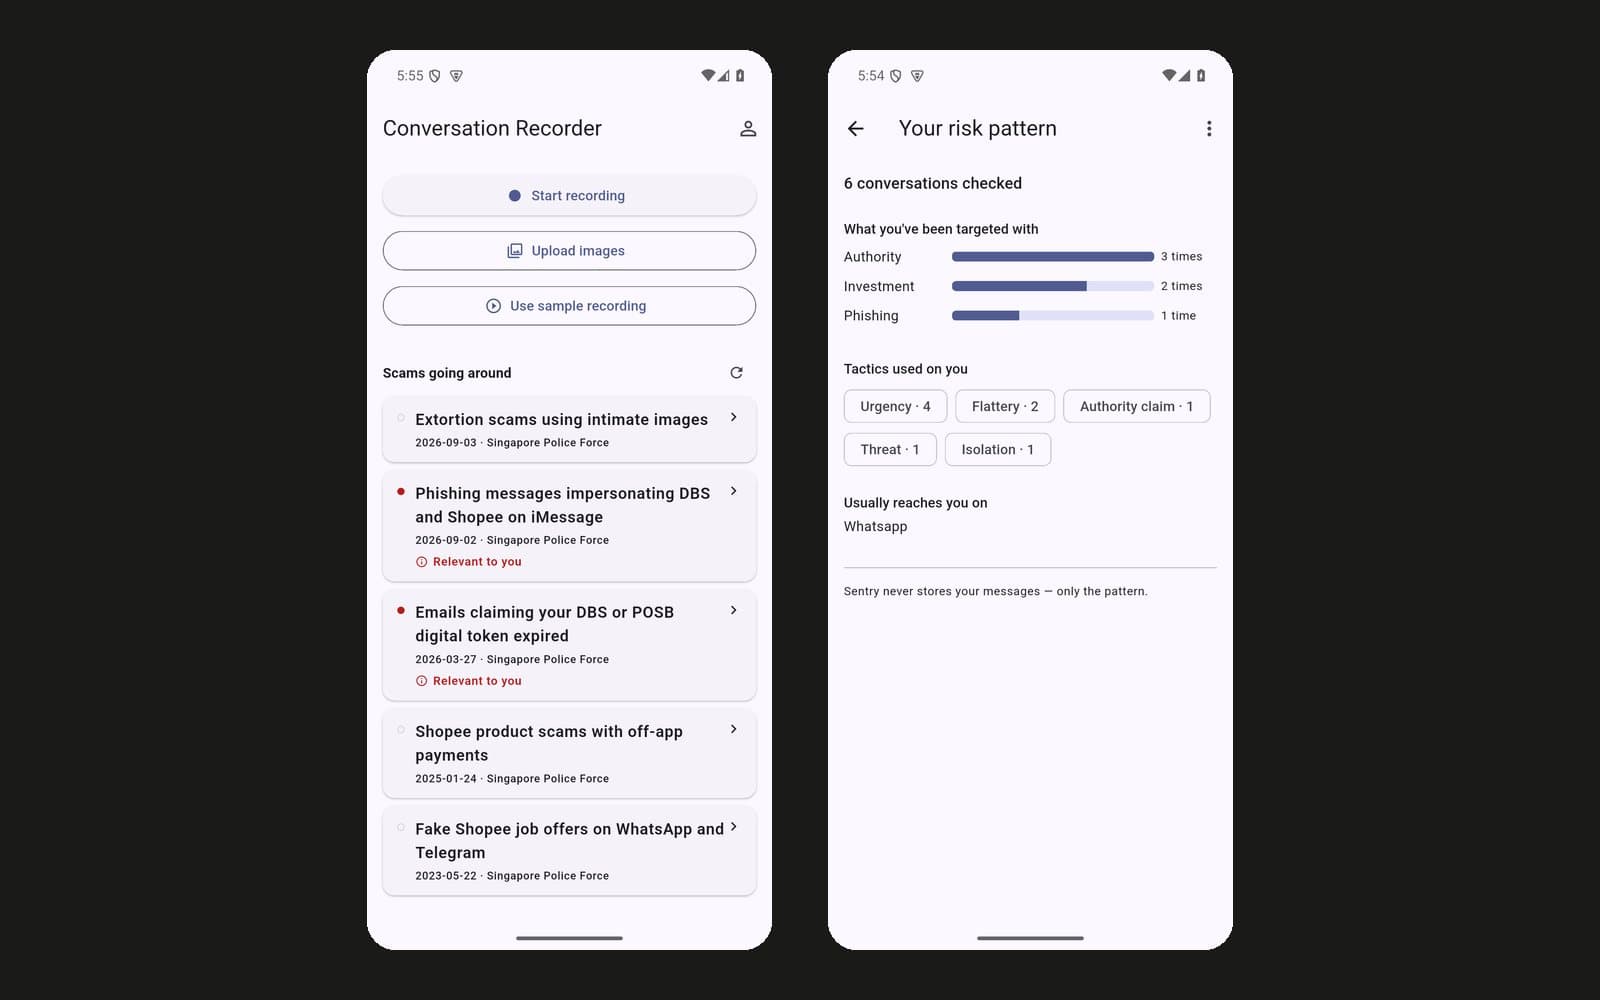
- DThe profile stores labels and counts only, never message text, and nothing records which user saw which advisory.
Hardest part
Keeping a language model useful without letting it decide anything that matters, when the text it reads was written by the attacker.
Outcome
Semi-finalist. Every verdict can be reproduced from stored evidence, explained check by check, and tested without an API key.
Screens